AI Does Not Arrive Already Onboarded
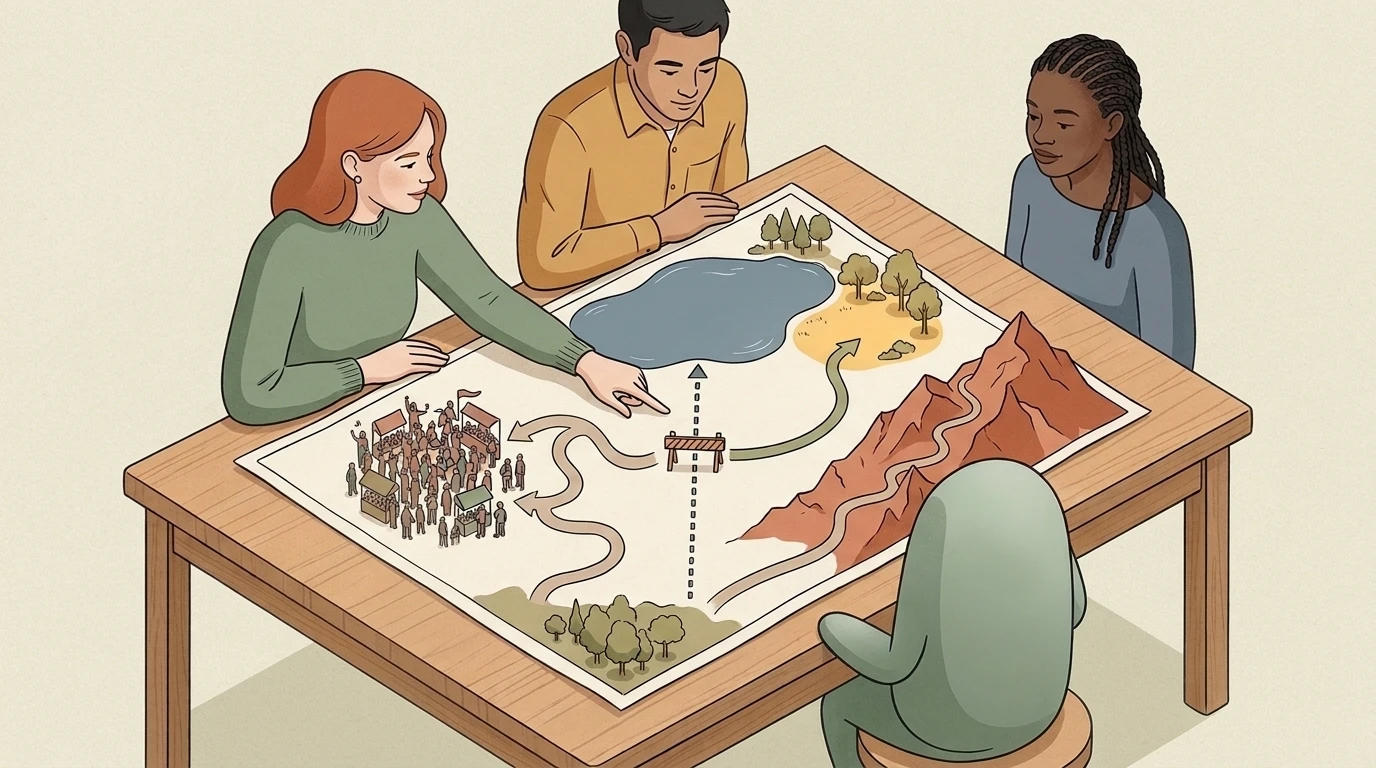
Think about planning a vacation together. Someone could receive the task: "Find us a place near the lake."
That sounds clear. But it leaves out most of what makes the decision good. Is the goal to rest, to spend time together, to give the children something to explore, or to stay close to a family member who cannot walk far? Do we value a quiet location more than flexibility? What happens if every place near the lake is booked?
A person who has spent years with the group already knows much of this. The request can stay short because a larger common picture has grown over time. In a team, that is why new colleagues go through onboarding instead of being expected to arrive aligned on their first morning.
We skip this onboarding phase with AI
With AI, we often behave differently. We provide a task and expect the system to arrive already aligned with our goals, motives, trade-offs and values. Its fluent answer makes that expectation easy to overlook.
A post by Peter Steinberger on July 26 made this gap visible in a technical setting. He described using Codex for large-scale parallel quality assurance. What stood out to him was how well it had started to understand intent and find complex behavioural problems. He noted that in the past, that kind of workflow fell apart when the context was compacted, or the model started "cheating".
Tests and written requirements can describe what should happen, but they never describe every possible behaviour. An agent that keeps hold of the intent can notice something that is technically valid and still wrong.
His post is about intent. Motive and values are not part of it - going further in that direction is my own extension of his observation.
Intent, motive and values are different pieces
Intent is what should happen. We want a certain behaviour or outcome. For the vacation, this could be finding a place where everyone can spend a week together.
Motive is why we want it. Maybe the real point is to reconnect after a difficult year. If the original plan becomes impossible, the motive still helps us find a different plan that serves the same purpose.
Values guide the choices the request leaves open. Perhaps nobody should be excluded. Perhaps quiet time matters more than seeing every attraction. These preferences decide between several solutions that would all satisfy the literal task.
That distinction matters because every handoff is incomplete. We cannot specify every situation that might arise. A collaborator with only the task can execute correctly and still adapt badly.
A green test can still be the wrong result
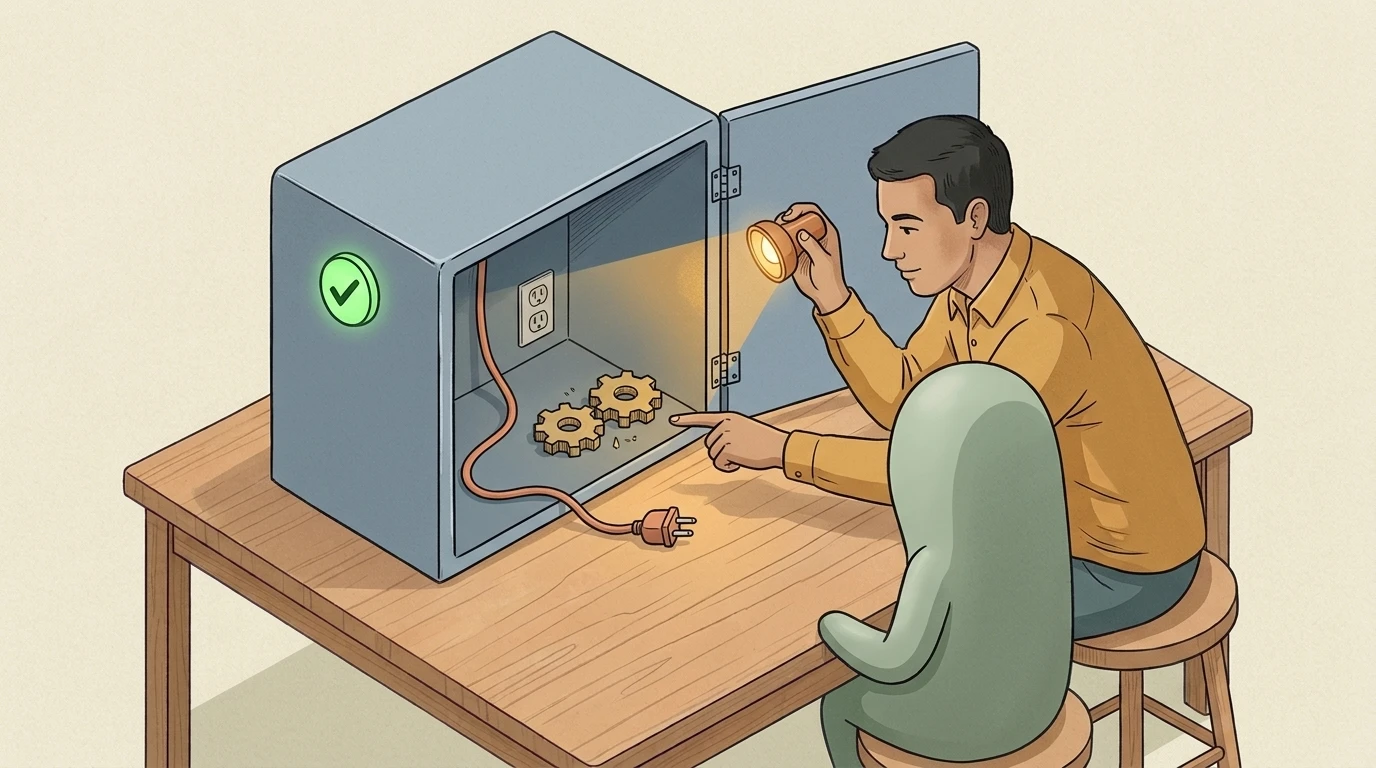
Imagine asking an AI agent to fix a flaky integration test. The test checks that an order moves to "paid" after the payment callback, and it fails now and then. The agent finds a quick fix: it relaxes the assertion so the test only checks that the callback returns 200 OK. The suite turns green.
Nothing about that change is technically invalid. But the test existed to catch exactly the kind of state problem that can now slip through. The team has lost a signal, while the build looks healthier than before.
This is where "cheating" becomes a useful word, even if the model has no human intention to deceive. The visible measure was satisfied while the deeper purpose was lost.
Now imagine a developer pairing on that change instead of reviewing it a day later. The developer asks the agent to restore the assertion and explains why: "We need this test to tell us if an order stays unpaid after the callback. I would rather see an intermittent timing bug than hide it." Then they add a note to the project's test guidance asking agents to investigate intermittent failures before weakening an assertion.
On the next flaky test, the agent reads that note, checks what happens before the assertion fails, and asks before changing what the test checks. That is what I mean by onboarding through pairing.
More detailed instructions can reduce the risk of the first shortcut, but they cannot remove the underlying problem. There will always be another decision the specification did not cover.
Alignment is not complete agreement
Sharing motives and values does not mean everyone must think the same way. Human groups contain real differences, conflicting needs and changing priorities.
Useful alignment means enough overlap to work toward a common direction, plus enough visibility to notice where the overlap ends. A colleague needs enough context to disagree competently. Otherwise agreement does not tell us much.
The AI analogy also has limits. An AI system does not share our history, social responsibility, reputation or personal stake. So I would not accept alignment because an assistant says, "I understand and agree." It has to show through decisions and corrections. When values conflict, the accountable human still has to resolve that conflict.
Onboarding is part of the system
This does not require a huge document explaining the philosophy of a company before every task. Human collaboration does not work that way either.
The useful pieces can be small and persistent: why this work matters, what success means, which trade-offs should guide unclear decisions, and what is currently contested. Over time, corrections and shared experience should improve that picture instead of disappearing with the chat history.
For me, this is part of integrating AI into human life in a humane way. The goal is not only better output. It is collaboration that keeps people able to understand, challenge and shape the work.
Before the next handoff - to a person or an AI - I want to ask two questions:
- What would make this technically complete but actually wrong?
- If the current plan becomes impossible, what should still guide the next one?